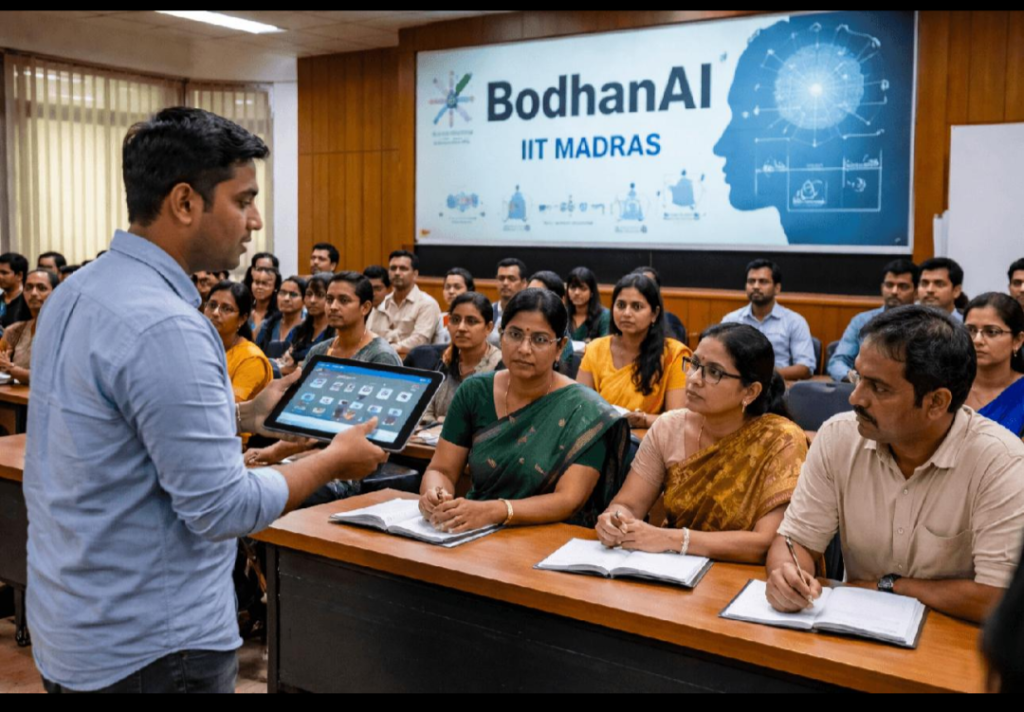
IIT Madras-linked Bodhan AI, in collaboration with AI4Bharat and NVIDIA, has introduced a suite of open-weight foundational AI models designed specifically around Indian-language needs. The models target speech recognition, text-to-speech, machine translation and optical character recognition (OCR), supporting India’s push toward multilingual AI, particularly in education.
Bodhan AI is a Centre of Excellence in AI for Education incubated at IIT Madras and supported by the Ministry of Education. It forms a core part of the Bharat EduAI Stack — envisioned as sovereign Digital Public Infrastructure for education.
Frontier global models often underperform in Indian languages. These open-weight models are released as Digital Public Goods, available both as downloadable weights and through hosted APIs on sovereign infrastructure.
Edtech companies, startups, researchers, universities and government agencies can deploy, adapt and fine-tune them without building foundational models from scratch. This reduces duplication and accelerates innovation across India’s multilingual ecosystem.
Principal Investigator Prof. Mitesh Khapra noted that the goal is to provide the best open models for developers to adapt and fine-tune, driving faster adoption of multilingual and multimodal AI. Partnering with NVIDIA enables state-of-the-art capabilities to reach the ecosystem more quickly.
Education Focus
The initiative also includes Student Tutor Bot (for Classes 6–12, aligned with NCERT/SCERT curricula) and Teacher Assistant tools. Students can interact via text or voice in 22 Indian languages for explanations, practice and assessments.
IIT Madras Director Prof. V. Kamakoti emphasised that India’s AI journey must be built on technology that understands India, creating sovereign infrastructure that serves linguistic diversity at scale.
This development strengthens India’s position in multilingual AI and supports equitable access to education and technology in regional languages.